
Discover how APIs power AI applications, AI agents,...
For years, businesses moving to the cloud mainly focused on three things: performance, scalability, and cost.
Today, there is another important question that software teams need to ask:
Where is our data actually stored and processed?
With cloud platforms, AI tools, SaaS applications, and global teams becoming part of everyday business, data can move across different countries without businesses always realizing how many systems are involved.
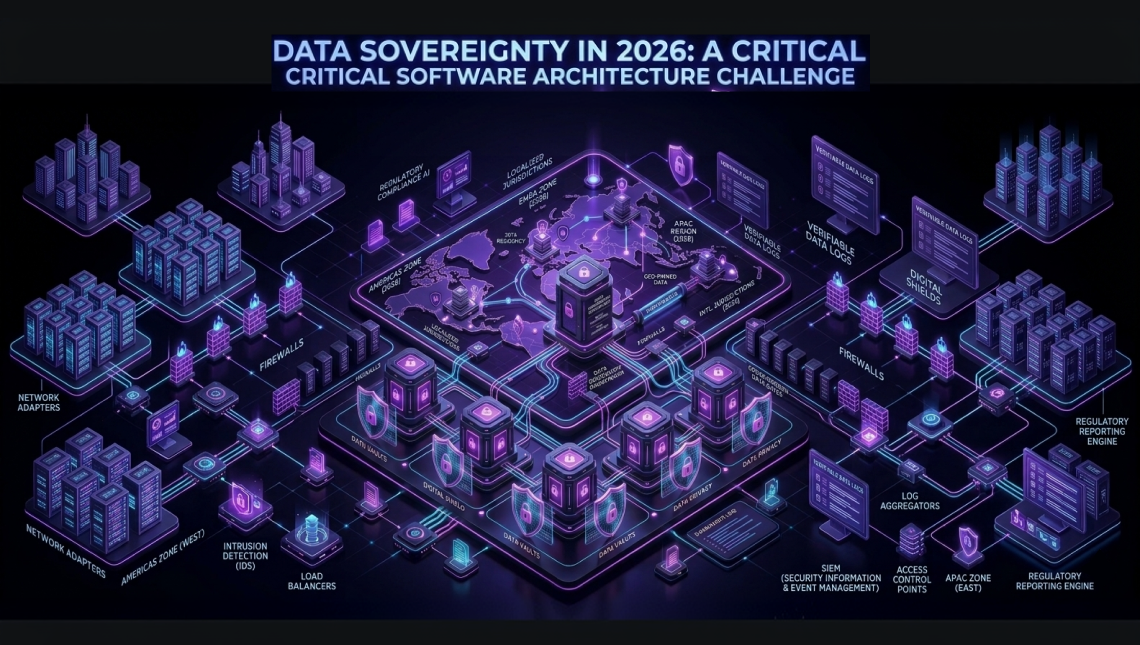
This is why data sovereignty has become an important software architecture challenge in 2026.
It is no longer just a legal or compliance concern. It can directly influence how applications are designed, where databases are hosted, how APIs work, and how businesses manage backups and third-party services.
What Is Data Sovereignty?
Data sovereignty means that data is subject to the laws and regulations of the country or jurisdiction where it is stored or processed.
For example, a company may store customer information in India. Depending on the type of data and applicable regulations, the organization may need to make sure that the information is stored, processed, transferred, and protected appropriately.
This is different from data residency, which simply refers to where data is physically stored.
The difference is important because data may be stored in one country but processed by a service located somewhere else.
Why Is Data Sovereignty Important in 2026?
Modern software applications are rarely built using just one system. A typical application might use:
- A cloud database
- Cloud storage
- An analytics platform
- Payment services
- Monitoring tools
- Customer support software
- AI APIs
- Backup systems
Each of these services can potentially interact with business or customer data.
Imagine a company's main database is located in India. However, its analytics platform processes data in Singapore, its backup is stored in another region, and an AI service processes customer messages elsewhere.
The company now has a much bigger data-flow problem to understand. This is one of the main reasons data sovereignty has become an architecture issue.
Cloud Architecture Needs a New Perspective
Cloud computing makes it easy to deploy applications across different regions. That flexibility is useful for improving performance and availability. However, businesses also need to understand where sensitive information is being stored and processed.
Instead of simply asking: "Which cloud region should we use?"
Architecture teams increasingly need to ask: "Which data can be stored or processed in each region?"
For some applications, this could mean using regional databases or keeping certain sensitive information within specific geographical boundaries.
The goal is not necessarily to create completely separate applications for every country. Instead, businesses can design systems that are region-aware.
AI Is Making Data Sovereignty More Complex
The rapid adoption of AI has added another challenge.
Businesses are now using AI for customer support, document processing, recommendations, content generation, analytics, and automation.
But whenever an application sends information to an AI service, the architecture needs to consider what information is being shared and where it is processed.
For example:
Customer → Application → Database → AI Service
If customer information is sent to an external AI service, the organization needs to understand the service's data handling, storage, processing, and security practices.
This makes AI integration an important part of data sovereignty planning.
Third-Party Services Matter Too
Businesses often focus heavily on their own infrastructure while overlooking third-party platforms.
A company might carefully choose where its database is hosted but forget about the other services connected to the application.
For example:
Application → Database → Analytics → Monitoring → Customer Support
Data may appear in logs, error reports, analytics dashboards, or support systems.
Therefore, software teams need to understand the complete data journey, not just the location of the primary database.
Backups Should Not Be Ignored
Data sovereignty also applies to backups and disaster recovery.
Suppose an application's main database is hosted in the required region, but automated backups are copied to another country.
The primary system may appear compliant, but the backup strategy could create a different data-location issue.
Architecture teams should therefore consider where the following are stored:
- Database backups
- Disaster recovery copies
- File storage
- Archived data
- Application logs
- System snapshots
A good architecture should know where every important copy of sensitive data exists.
Data Classification Makes Architecture Easier
Not every piece of data needs the same level of protection. Businesses can make the process easier by classifying their data.
For example:
- Public data may be distributed globally.
- Internal business data may have moderate restrictions.
- Personal information may require stronger regional controls.
- Highly sensitive information may need strict storage and processing boundaries.
Once data is classified, architects can decide where each category can be stored, processed, and transferred.
This approach is usually more practical than applying the same restrictions to every piece of information.
How Can Businesses Build Data-Sovereign Applications?
Data sovereignty does not require businesses to completely redesign their technology stack. Instead, teams can start with a few practical steps.
1. Map the Data Flow
Identify where data is collected, stored, processed, transferred, and backed up.
2. Choose Cloud Regions Carefully
Select infrastructure locations based on business and regulatory requirements, not just performance.
3. Review Third-Party Services
Understand what information external platforms receive and where that information is processed.
4. Protect Sensitive Data
Use encryption, access controls, secure authentication, and appropriate key-management practices.
5. Review Backups
Make sure backup and disaster-recovery systems follow the same data-location requirements.
6. Build with Regional Flexibility
Design applications so that regional requirements can be introduced without rebuilding the entire system.
A Simple Data Sovereignty Checklist
Before launching a global application, ask:
- Where is our data stored?
- Where is it processed?
- Can it cross international borders?
- Where are our backups located?
- Which third-party services receive it?
- Does our AI provider process sensitive information?
- Where are application logs stored?
- Who can access the data?
- Can we isolate data by region if requirements change?
These questions can help identify problems before they become expensive architecture changes.
The Future of Data Sovereignty
Data sovereignty is likely to become an even bigger consideration as businesses adopt more cloud services, AI systems, and globally distributed applications.
The focus is shifting from simply "keeping data secure" to also understanding where data exists and who controls it.
For software teams, this means data sovereignty should be considered during architecture planning—not after the application is already built.
Conclusion
In 2026, data sovereignty is no longer something that only legal and compliance teams need to think about. It has become part of modern software architecture.
Cloud infrastructure, AI services, SaaS platforms, APIs, backups, and analytics can all influence where business and customer data travels.
The best approach is simple: understand your data, map its journey, and design your architecture accordingly.
A future-ready application is not just scalable and secure. It also knows where its data can go, where it should stay, and who is allowed to access it.